We checked 65 of our AI video clips for impossible physics. 14 failed.
A body through a solid thing, an object from nowhere, one thing turning into another. What the research says, how often it happens in our own product, and why our automatic judge saw none of it.
By Alper Mutlu Toksöz, founder, runimePublished . 13 min read. Measured 19 Nov 2026 on 65 clips.
- 14 of 65
- clips had a defect a viewer would notice: 22%, 95% interval 13% to 33%
- 12% and 30%
- the same rate in takes members kept, and in takes they replaced
- 0, then 3 of 14
- defects our automatic judge caught, before and after we changed its questions
The question
runime makes animated films from a script. It writes the shots, draws a still for each one, and hands the still to a video model that turns it into a few seconds of motion. On 19 November a member's film had a shot in which a character walks up to an anvil and, for about three quarters of a second, walks through the end of it.
The founder's first reaction was that competitors had solved this and we had not. That sentence holds two claims, and we had a number for neither. Has anyone solved it? And how often does it happen to us? This note is what we found, with the data.
The events we mean are the ones a person calls impossible without thinking. Research on intuitive physics names the rules they break1:
- Solidity. A body or an object passes through something solid, sinks into it or fuses with it.
- Permanence. A person or an object comes into existence where nothing was, or stops existing without leaving.
- Immutability. A thing turns into another thing: a different shape, size, count or design. We call this one morph.
The anvil clip belongs to a member, so it is not shown here. We publish counts from members' films and nothing else of theirs. Every picture on this page comes from films made in the founder's own account.
Nobody has solved it
We read the benchmarks of the last two years and the release notes of every engine we call. No model and no product has a published low rate of these events, and the independent measurements point the other way.
Those prompts were written to be hard: collisions, pouring, breaking. Ordinary film shots are calmer, so the rates are not ours. What carries over is the shape of the result. Pass-through is not even the most common failure. In WorldModelBench, objects changing shape was a more common violation than objects passing through each other3, which is what we later found in our own clips.
The vendors do not claim otherwise when they are specific. Runway's own page for Gen-4.5 lists objects that vanish or appear after being hidden as a known limitation7. ByteDance lists the physical plausibility of complex motion for Seedance 2.58. We found no vendor that publishes a defect rate.
What looks solved is selection
If the models make these mistakes, why do the showcase films look clean? Because someone threw the bad takes away. Where makers have said how many generations they burned per shot they kept, the numbers look like this.
The newest models did not close the gap: the 64 to 1 film was made in 2026, on an engine that still ranks near the top. The ratio follows the quality bar more than the model. The vendor that published the 4 to 1 figure says ad-grade work commonly takes 10 to 40 prompts per usable clip9.
By default our pipeline renders one take per shot and puts it in the film. No professional source we found reports working at that ratio. So the founder's sentence was half right. Others have not solved the physics. They select, and by default we did not.
What we measured
14 of 65 clips, 22%, carried a defect a viewer would notice (95% interval 13% to 33%). Roughly one clip in five. That is far below the benchmarks above, and the reason is not that our engines are better. Most of our shots are calm: dialogue, a small gesture, one camera move.
All 65 clips: 22%
All clips: 14 of 65 clips, 22%. 95% interval 13% to 33%.
Read the engine rows with care. They are not a ranking. The groups come from different months and different kinds of shot, the Veo Fast clips have no character in them at all, and with 6 to 30 clips per group the intervals overlap almost everywhere. The sample was built to estimate the overall rate, and that is the only number here we would repeat without its interval.
Members already select. Of the takes a member kept, 4 of 32 had a noticeable defect (12%). Of the takes they replaced, 10 of 33 did (30%). People are doing by hand, and paying for it, the selection the film industry does on purpose. The two intervals overlap (5% to 28% against 17% to 47%), so the size of that gap is not settled. Its direction is what you would expect.
Morphing is the largest class, not pass-through. Counting every mark, including the ones too small to notice, 16 clips carry at least one. A morph is in 7 of them and a pass-through in 3. The anvil is real, but things quietly becoming other things are about twice as common. Shots with a camera move had a noticeable defect 25% of the time, against 14% for shots without one.
We are not publishing the label file. Each row describes what happens in a member's clip. The counts on this page are all of it that is ours to show.
Two of them, frame by frame
A rate does not show what these look like, so here are two. Both are takes the founder replaced in his own films, picked by hand because they are clear. They are not in the sample and they do not move any number above.
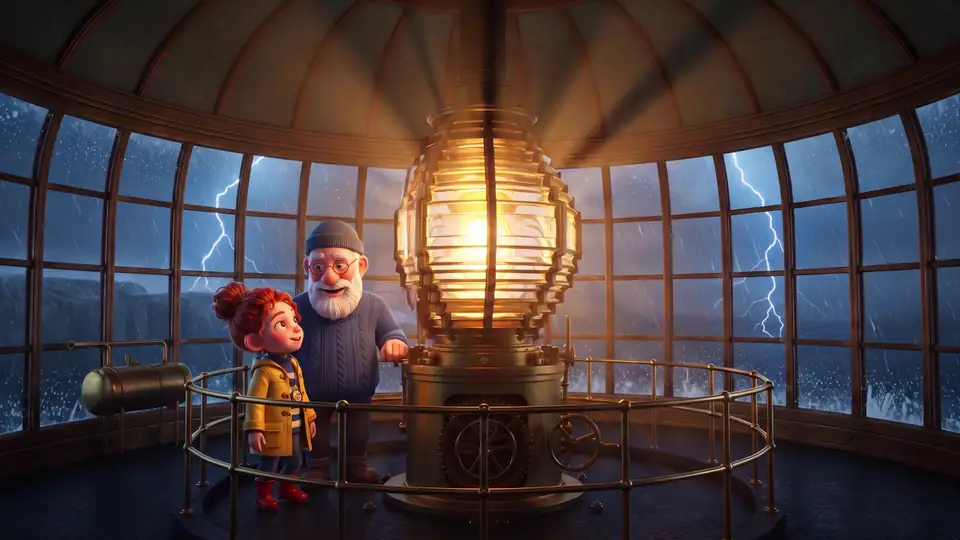
Morph: a lighthouse lens turns into another object
The lens starts as a tall barrel of stacked glass rings. At 0.25 s a flat round face grows on its side, and by 1.0 s the barrel is gone: it is a round disc with a flame in it, and it stays one.
The event covers 4 of these 24 frames, from 0.25 s to 1.00 s.
A replaced take from Light the Way Home, our sample film. Engine: Grok.
Neither is subtle once you look, and both pass at a glance. In the first clip the light gets brighter at the moment the lens changes, which is the motion your eye expects. In the second the new figure fades in behind a moving one. Events like these last between half a second and two seconds. That matters for the next section.
Our judge caught 0 of 14
The clips we render are checked by a vision model. It looks at mouths, at who is in the shot, at the style and at motion, and a failed check buys one corrective re-render. We ran its records against the labels. On the 65 clips it had raised 0 physical flags. It caught 0 of the 14 defects.
The code says why, and none of the three reasons is that the model is weak.
- It was never asked. The main judge asked whether a person appears who should not be there, and whether motion slides, floats or morphs. It had no question about a thing that appears, a thing that vanishes, or a body that passes through an object.
- The one question about contact was about doors. A second judge had a single answer for how bodies meet the set, with five options built around openings. On a shot with no door or hatch, "no opening involved" is a true answer while a body walks through an anvil.
- It saw too few frames. Since 17 November the judge reads still frames, and the standard strip is 1.5 frames a second: 9 frames for a 6 second clip, one every 0.67 s. The anvil pass-through lasted from 0.95 s to 1.7 s. An object that pops into existence is new in a single frame.
The research agrees that asking a model whether a clip looks physically right does not work. In Physion-Eval the best general vision model failed to flag more than 74% of third-person clips that people had marked as glitched, and more frames or more thinking did not help2. On rendered pairs of possible and impossible scenes, the vision models tested scored 52% to 56% where people score 96%1. What does help is structure: one question per rule. That cut one judge's bias on solid-body laws from 40% to 22%13.
So the judge now reports facts instead of a verdict. It lists every intersection, every arrival, every departure and every change, each with its time, and our code turns those lists into three flags. It reads 4 frames a second, 12 to 40 of them, at 384 px wide instead of 512. A flag is asked again twice and only counts when two of the three answers agree. A shot whose story is the impossible thing itself is exempt.
- The judge is asked to list
- Every solid thing that turns into something else during the clip: another shape or size, another count (one becomes two, two merge into one), another material, design or identity.
- It is told this does not count
- A change of pose, expression or lighting, an object turning to show another side, an effect changing, or a change the planned action asks for.
- Our code raises the flag when
- The list has at least one named entry.
- Field
changed
Read against
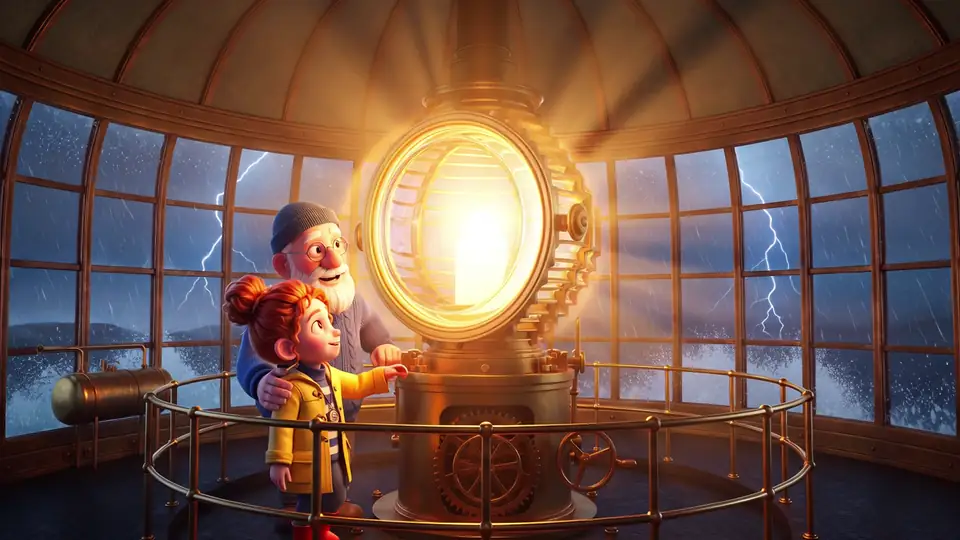
changed: [{ what: "the barrel lens of stacked rings becomes a flat round disc", atSec: 0.25 }]Flag: morphIt is not the lens turning to show another side: the stack of rings is replaced by a different object.
Then we measured it. We replayed the new judge on the same 65 labelled clips, exactly as production runs it. It caught 3 of the 14 defects (21%), and 3 of its 5 flags were right (60%). We ran it twice and got the same counts.
That is better than 0 and not good enough. Our bar for letting a question spend money on a repair is that 80% of its flags are right. At 60%, two repairs in five would re-render a clip that was fine. So the new questions run in shadow: every clip is judged and the answers are recorded, and nothing is repaired or shown to the member because of them. The misses are mostly morphs and pass-throughs that last one or two frames. It is the miss rate the literature told us to expect.
What we changed
Three things shipped on 19 November. Two act before the clip is rendered, because detection after it is the weak link.
A reach check on the still. When we traced the anvil shot, the plan had the character put his hands on the anvil. The still we drew put him a body's width to one side of it, facing the camera. The action had no reachable start, and the video model got him there the shortest way: through the end of the anvil. Now, when a shot's plan has a body touch something, the still is drawn with that body beside the thing, on the near side, within arm's reach. The model that already reviews every still answers one more question: can the planned action start from this pose without crossing anything? If not, the still is drawn again. A still costs a small fraction of a clip, so this is the cheapest place to stop the anvil case.
A physical timeline before each clip. A vision model looks at the first frame and the planned action and writes two to five timed steps: where each body is, which way it goes around what, where the hands land, and what stays still. That text goes into the video prompt. On the anvil still it routes the character one step to the side, around the end of the anvil, before his hands come down. The idea is from the Physics-IQ leaderboard, where several teams report 6 to 12 points from having a language model narrate the outcome from the start frame14. It costs about one cent per clip. Its effect on our clips is not measured yet, because measuring it means rendering.
The judge that asks. Described above: three event questions, 4 frames a second, in shadow until its flags are right 80% of the time.
What we decided not to do
Paid test renders. Two experiments were costed at about 55 dollars together: an end keyframe on shots where a body changes place, and a head-to-head of engines on our riskiest shots. The evidence for both is good. Planned keyframes took an unmodified open model from 32.2 to 55.0 on Physics-IQ Verified15, and two engines we can call come first or second in the independent physics rankings that include them. We did not run them. The founder's reasoning was that paid tests have no natural end, and that he would rather look at what members actually make. From here every measurement comes from what members make: the shadow judge's records, replaced takes, dislikes and complaints. That is slower, and it means we cannot say today whether either idea works on our shots.
Two takes per shot. If 22% of takes are defective and the failures were independent, a perfect chooser with two takes would ship a defect about 5% of the time. It is the same thing members already do by hand. But an extra take on the risky half of the shots adds about 30% to the video cost of a film, and members pay for renders at a price tied to our cost. And we do not have the perfect chooser: the judge that would pick between the takes is the one that catches 3 of 14. Selection with a weak selector multiplies cost without buying much. In one study a small vision model used as the selector left the result 3.6 points lower than no selection at all16. So this is a pricing decision, and for now the answer is no.
More physics in the prompt. Our prompts already say that nothing passes through anything solid, that nothing pops in or out, and that no object turns into another. Measured on other models, naming a physical law in the prompt showed no reliable gain and sometimes a loss17. We stopped adding words.
Re-rolling as the repair. Our corrective re-render sends the same shot to the same engine with the faults listed at the top of the prompt, and keeps the new clip only if it is strictly better. Across the 73 attempts we have a record of, it was kept 3 times. A second roll of the same dice mostly lands the same way.
Limits
- Small groups. 65 clips give the overall rate an interval of 13% to 33%. The engine groups have 6 to 30 clips each and cannot be compared with each other.
- The labellers were models. Vision models read frame sheets from a written brief. That is the same kind of reader the literature says misses most glitches, although reading stills slowly with crops may be an easier task than judging a playing clip. 13 of the 14 defects were marked "probably" noticeable, not "yes". A person may count fewer, or more.
- Almost no double labelling. 4 clips were labelled twice. The two labellers agreed on the clear cases and split on the borderline ones. That is too few to put a number on agreement.
- One day, one product. The clips come from one pipeline, with its own prompts and its own mix of calm shots. The rate says nothing about the engines in general.
- The fixes are unmeasured. The reach check and the physical timeline are live, and we have not yet shown that they lower the rate.
The next step is the obvious one: a person labels 30 of the same clips against the same brief, so we learn how far the model labels can be trusted. When there is something new to report it will be added here with its date. The date at the top of this note will not change.
Sources
Each with the date of the work and the day we read it. Numbers about our own films come from our own records, described under What we measured.
- Bordes et al., IntPhys 2: benchmarking intuitive physics understanding in complex synthetic environments. arXiv 2506.09849, 2025.arxiv.org/abs/2506.09849Read
- Zhang et al., Physion-Eval. arXiv 2603.19607, March 2026.arxiv.org/abs/2603.19607Read
- Li et al., WorldModelBench. NeurIPS 2025, arXiv 2502.20694, 2025.arxiv.org/abs/2502.20694Read
- Thozhiyoor et al., Principia. arXiv 2609.04200, September 2026.arxiv.org/abs/2609.04200Read
- Physics-IQ benchmark maintainers; Rädsch et al., Physics-IQ Verified leaderboard and method paper. GitHub README; arXiv 2606.18943, 2026, newest row 12 October 2026.github.com/google-deepmind/physics-IQ-benchmarkRead
- Cui et al., Do Joint Audio-Video Generation Models Understand Physics? (AV-Phys Bench). arXiv 2605.07061, 2026.arxiv.org/abs/2605.07061Read
- Runway, Introducing Runway Gen-4.5. Runway Research, 1 December 2025.runway.com/research/introducing-runway-gen-4.5Read
- ByteDance Seed, Introducing Seedance 2.5. ByteDance Seed blog, 31 July 2026.seed.bytedance.com/en/blog/one-take-creation-flexible-referencing-introducing-seedance-2-5Read
- invideo, How many AI video generations do you need per usable shot?. invideo FAQ, page updated 27 July 2026.invideo.io/faq/how-many-ai-video-generations-do-you-need-per-usable/Read
- eWeek, Report on the Kalshi NBA Finals ad, quoting its maker. eWeek, 16 June 2025.www.eweek.com/news/ai-ad-kalshi-nba-finals/Read
- CineD, Report on the feature Hell Grind, with the maker's figures. CineD, 28 May 2026.www.cined.com/hell-grind-the-95-minute-ai-feature-cannes-2026-says-it-never-screened/Read
- fxguide, Actually using Sora, an interview with the makers of Air Head. fxguide, 14 April 2024.www.fxguide.com/fxfeatured/actually-using-sora/Read
- Lin et al., PhyGround. arXiv 2605.10806, May 2026.arxiv.org/abs/2605.10806Read
- Physics-IQ Verified submitters, Leaderboard rows with and without prompts rewritten by a language model (pull requests 87 and 90). GitHub, 2026.github.com/google-deepmind/physics-IQ-benchmark/pull/87Read
- O'Mahony et al., K2V. arXiv 2611.17324, 12 November 2026.arxiv.org/abs/2611.17324Read
- Yuan et al., WMReward. arXiv 2601.10553, 2026.arxiv.org/abs/2601.10553Read
- Guo et al., T2VPhysBench. arXiv 2505.00337, 2025.arxiv.org/abs/2505.00337Read
runime is the product these notes come from. It turns a script or an idea into an animated film. See what it does